

Learning semantic representations for 3D Gaussian Splatting has recently emerged as a promising direction for 3D scene understanding. However, existing 2D-to-3D semantic lifting approaches rely primarily on 2D segmentation supervision and lack object-level priors, causing the learned representation to be driven by local mask evidence rather than holistic object structure. In this paper, we present VLSplat, a vision-language guided approach for object-centric semantic lifting in 3D Gaussian Splatting. Our method augments mask-based lifting with object-level semantic priors derived from vision-language models and refines Gaussian representations using an object-group scene graph. The refinement is performed through two language-guided modules: intra-group refinement suppresses semantic noise within object groups, while inter-group acquisition expands object support regions by incorporating structurally relevant candidates from neighboring groups. Extensive experiments on indoor scene datasets demonstrate that VLSplat improves semantic consistency and structural completeness.
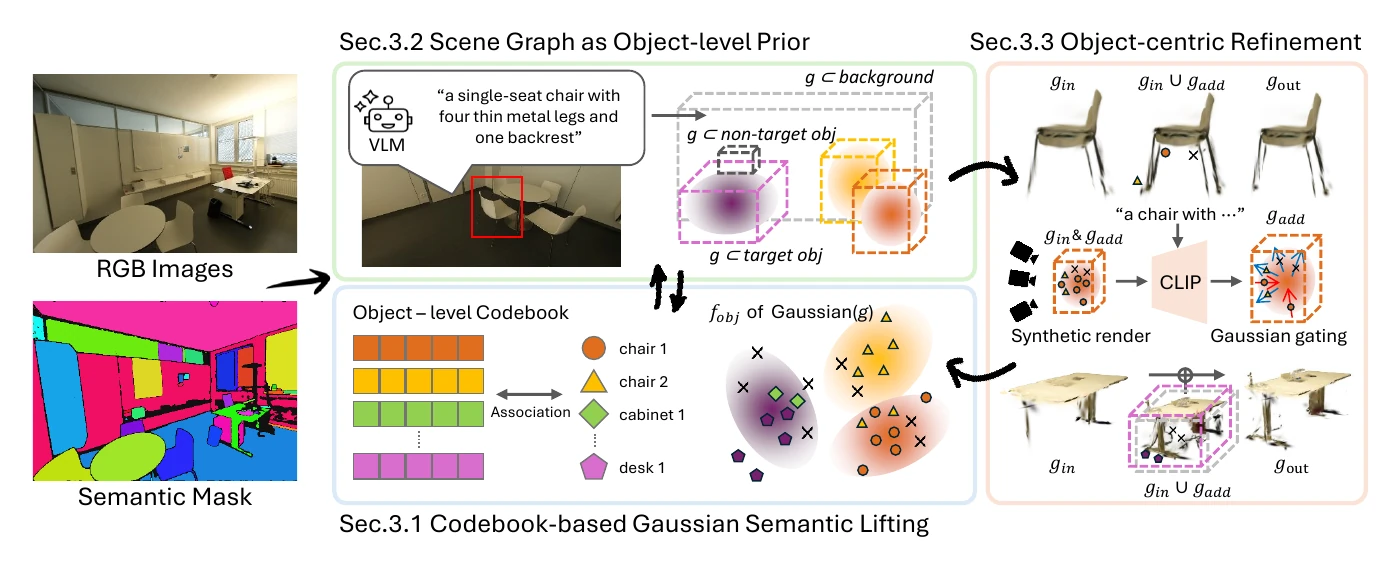
Hybrid SAM3 (text-prompted) + SAM2 masks supervise Gaussian features associated with an object-level codebook, giving coarse object groups.
Each group becomes a node with an anisotropic-connectivity ROI, a category and a VLM-generated object description; overlapping ROIs form edges.
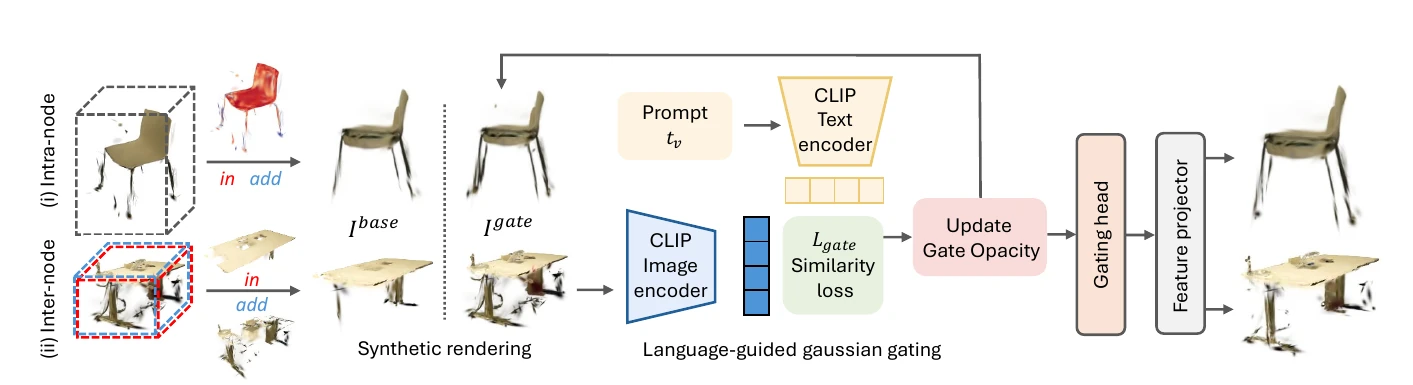
Intra-node refinement removes noisy Gaussians; inter-node acquisition recovers missing parts from neighbors — both decided by CLIP-guided gates on synthetic object views.
Semantic maps rendered from the 3D Gaussians at fixed camera views. Drag the bar to compare PanoGS (left) with VLSplat (right); pick a view below.
| Method | ScanNet++ | Replica | ||||||
|---|---|---|---|---|---|---|---|---|
| mAcc | mIoU | mAcc | mIoU | |||||
| Thing | Stuff | Thing | Stuff | Thing | Stuff | Thing | Stuff | |
| LEGaussian | 27.09 | 33.73 | 20.89 | 13.19 | OOM | |||
| OpenGaussian | 19.09 | 37.69 | 18.33 | 26.10 | 12.89 | 9.32 | 12.03 | 7.46 |
| LangSplatV2 | 65.69 | 57.82 | 61.32 | 39.94 | 66.88 | 56.40 | 59.64 | 35.80 |
| Unified-Lift + Ours | 64.77 | 74.99 | 64.42 | 68.63 | 65.99 | 67.42 | 65.93 | 65.55 |
| VLSplat (Ours) | 70.31 | 74.09 | 69.81 | 67.79 | 68.69 | 68.11 | 68.59 | 67.75 |
Predicted semantics on fixed 3D points. Orbit / zoom with the mouse; drag the bar to compare PanoGS (left) with VLSplat (right).
| Method | ScanNetV2 | Replica | ||||||
|---|---|---|---|---|---|---|---|---|
| mIoU | mAcc | PRQ(T) | PRQ(S) | mIoU | mAcc | PRQ(T) | PRQ(S) | |
| OpenGaussian | 29.73 | 41.69 | – | – | 32.56 | 38.81 | – | – |
| PanoGS | 54.50 | 74.98 | 35.65 | 30.32 | 56.91 | 68.27 | 35.76 | 64.60 |
| VLSplat (Ours) | 40.49 | 59.45 | 27.27 | 16.48 | 64.03 | 74.34 | 47.87 | 37.28 |
| VLSplat (Ours) † | 61.89 | 79.12 | 46.18 | 27.80 | 72.20 | 80.37 | 54.80 | 38.21 |
† localized object-level evaluation within scene-graph ROIs.
@inproceedings{jeon2026vlsplat,
  title     = {VLSplat: Vision-Language Guided Object-Centric 3D Gaussian Splatting via Scene Graph},
  author    = {Jeon, Yuntae and Jeon, Younho and Jin, Sujin and Jo, Sungho and Park, Seunghee},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026}
}